In the Forma protocol every node does its own job. To avoid spending effort on needless preparation, we need a selection that is independent, fast and cheap: which ready-made role fits this task. At our side that choice is made by Jev, a decision model. It does not write text; it returns a typed answer with probabilities.
Every Node Does Its Own Job
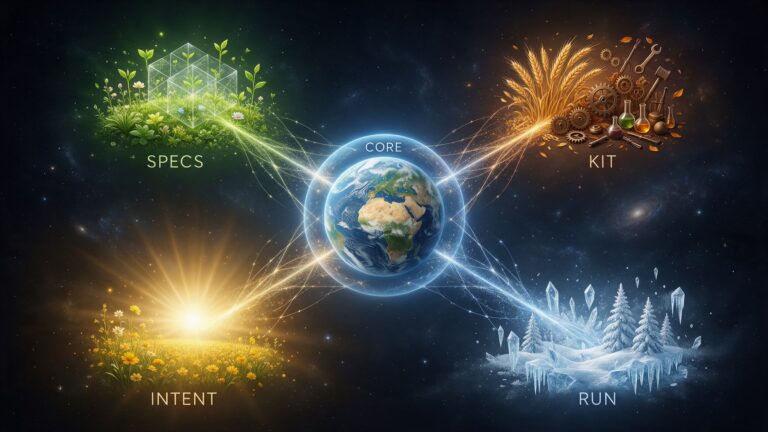
Five nodes share the work like this:
Intentholds the idea and accepts the result.Speccuts the goal into tasks and groups them into waves. In two or three passes it lays out several waves, so the work follows a plan instead of going in blind.Kitprepares the environment for the executor: role, skill, tool, access, data, model. It does not do the work itself, it prepares it.Runexecutes. Most of the time in the protocol it isRunthat is working.Coregives the verdict on the cycle.
The key word here is "prepares". Kit is neither an executor nor an evaluator. Its product is a role: a profile with "takes / does not take" criteria, skills and permissions, which Run can start working from right away.
The Problem: Kit Stood at Every Step
Work in a project is often repetitive. One role fits most tasks of the same kind, and a project accumulates ten or twenty of them for different kinds of work: building a page, writing text, a PHP probe, a visual check, a mechanical run.
Previously Kit was called on every card. It read the task, compared it with what already existed and assembled the kit. In most cases it created nothing new: a suitable role was already there, and it only confirmed that. That work piles up with every card, costs tokens and time, and adds nothing.
The solution is obvious: create a role once and use it many times. But then a question appears: who chooses the role for the next task, and how? If Kit chooses, we are back at the same checkpoint booth. The choice has to be made by an independent source: fast, cheap and more accurate than the kit-maker's own judgment of itself.
Plumb and Jev
This work is done by Plumb. It is not a sixth node: it takes no cards, decides nothing and confirms nothing. It reads the scrubbed card cut by Spec and the role catalog, and returns numbers. The decision is made by Spec, using thresholds from PROJECT.md.
Why "Plumb"
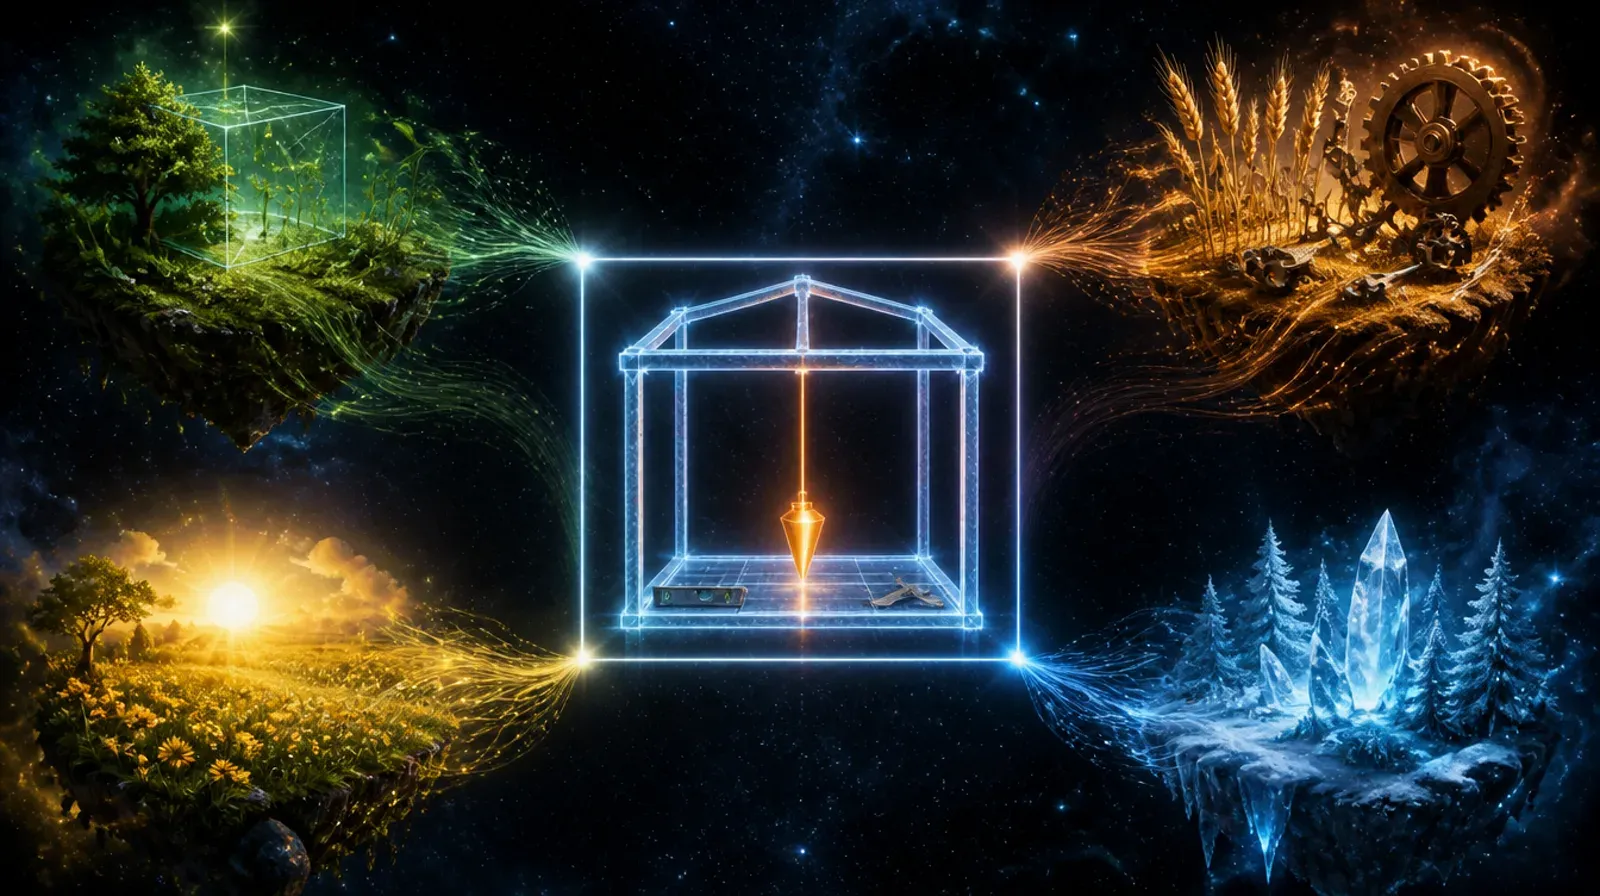
A plumb line is a string with a weight: it shows true vertical, and it is what you check a wall against to see whether it stands straight. It does not build and does not repair; it only says: straight or crooked. It is the same here. Forma raises structures out of cards, roles and nodes, and Plumb checks whether everything lies straight: does the role fit the task, is the task itself clear. For a structure to stand like a house and not sprawl, it has to be checked against the plumb line all the time.
A plumb line measures vertical, while a level measures horizontal: both catch skew, each along its own axis. Here, Plumb is the measuring function: does the role fit the task, and is the task itself clear. Jev is not the plumb line itself but whoever takes the measurement, that is, Plumb's executor. Before, the built-in small model did this work, and if the executor is swapped, Plumb stays Plumb. Plumb is the instrument, Jev is the hand that holds it.
Three Questions in One Call
Jev can serve as Plumb's executor. It answers three questions in a single call:
- Which role is closest (
choice): a role and a probability for each role. - How clear is the task (
score): a rating from 0 to 4. - Does the leading role take this task (
noul): a probability from 0 to 1.
Then there are two outcomes:
- A role fits. The card goes straight to
Run, and the role is written into its kit.Kitis not called at all. - No suitable role exists. Only then is
Kitbrought in. It creates an exact role for this kind of work and checks it with the same call, using the Jev score as its guide.
This way Kit is used only when needed. It creates roles, while an independent party chooses between them.
What Jev Is
Jev is the flagship model of TypeSafe and the first model of the System One class. The name comes from Daniel Kahneman's book "Thinking, Fast and Slow": System 1 is fast, intuitive judgment, System 2 is slow and deliberate. System One makes fast, narrow, "first glance" decisions that a program can use immediately.
TypeSafe's main idea: language models were built to write text for people. When code needs a judgment, you have to force the model to produce a structure and then parse its answer back. Jev removes this detour: it accepts text (strings, JSON, arrays of text) and returns typed values and probability distributions. You can branch, sort and route directly on them.
Questions come in three types, called primitives:
| Primitive | Question | What it returns |
|---|---|---|
| Choice | Which of the options? | the option, a probability for each, confidence |
| Score | Where on the scale? | the position, a probability for each level, confidence |
| Noul | Is the statement true? | the probability of "yes" (0–1) |
Calibrated Probabilities
Jev is trained so that its probabilities reflect real uncertainty. Calibration is measured across groups of predictions and does not guarantee that any single answer is correct. For Plumb this matters: a confidence threshold makes sense because 0.9 here really means "confident", not "it just came out that way".
Confidence as an "I Don't Know" Signal
Every choice and score answer carries confidence, a number from 0 to 1. If all the probability is concentrated on one option it is close to 1; if it is spread evenly it is close to 0. According to TypeSafe's documentation, the ability to honestly say "not sure" is the foundation of a system you can trust. Three paths are suggested:
- High confidence: act automatically.
- Medium: act carefully: confirm or verify.
- Low: do not act: hand it to a person, clarify, or switch to another system.
In our route this maps one to one: high, and the card goes to Run; low, and it goes to Kit to create a role or to Spec to be restated. The exact thresholds are set by a person in PROJECT.md.
Atomic Questions and Parallelism
Each question in a request is evaluated in parallel and independently of the others, against the same description of the situation. So adding questions barely changes the response time and does not create "context overload". The documentation advises asking narrow questions that a knowledgeable person could answer in a couple of seconds, and splitting compound judgments into separate questions assembled in code. That is how Plumb is built: three separate questions, and Spec assembles the decision.
One more detail from the documentation: the model sees the option names and their descriptions, so the descriptions must clearly distinguish one option from another. In our case a role is described by "takes / does not take" lines, and these same lines serve as the criteria for Jev. A well-written role is also a well-readable option.
Price and Limits
- The model is
typesafe/jev-1.13, called through the OpenRouter Decisions API (POST /api/alpha/decisions), not throughchat/completions. - Only input is billed: $0.042 per million tokens, output is free. Every response contains
usage.cost, the actual price of the call in dollars. - Context is on the order of 32 thousand tokens (per the documentation) for the situation description and the questions.
- It accepts text only. Images, audio and video are not supported yet.
- It does not write text, code or explanations. If a written justification is needed, the decision can be passed to a chat model, and on low confidence to a person.
How It Works in the Protocol
Spec cuts (waves, 2–3 passes) → scrub → Jev → choice / score / noul → Spec checks against thresholds
                                                  ├─ role fits → Run
                                                  ├─ no role → Kit creates a role → Run
                                                  └─ low clarity → Spec restates once
Scrubbing happens before sending. A script, not a model, builds the input from the card's five fields only. It replaces values from VARS/ and .env with their names and masks addresses, tokens and paths. If anything resembling a secret remains, nothing is sent and the card goes to a person (prohibition 17).
Fallback instead of failure. No key, a bridge error or a scrubbing refusal: the caller then uses the built-in small model, and the reason is written into the card's history. The attempt is not recorded as a Jev reading.
A person holds the levers. The executor is chosen by a word in PROJECT.md (haiku by default, jev by a person's decision). The call limit per cycle and the thresholds are set by a person. An executor gets the right to decide only after being measured on closed cards.
What This Gives
Kitstops being a checkpoint booth. It creates roles, and only when no suitable one exists. Before creating a new roleKitchecks it for a duplicate with the same call: if an existing role clears the threshold, it is extended rather than copied. So the catalog grows tidily, and the share of cards that needKitfalls over time.Runworks most of the time. Preparation became a one-time job, execution became mass work.- The choice is independent. Jev took no part in the slicing and will not assemble the role, so its "there is no such role" is more honest than the kit-maker's self-assessment.
- Cheap and fast. One call with three questions costs a fraction of a cent: a card plus the role catalog is a few thousand input tokens at $0.042 per million. The exact price comes from
usage.costand is written into the spend line. - Discrepancies become a diagnosis. Every reading stays as a line in the card's history.
Coreevaluates the evaluator itself: how many cards were accepted on the first attempt, where Jev confidently named a role but the kit was assembled differently, where a low score fell on a clear task. From this it gives its verdict on how effective the selection was, whether the role catalog is sufficient and whether the thresholds are right.
The result is a division of labor: Spec cuts, Jev picks the role, Kit creates roles, Run executes, Core judges how good the choice was.
What Jev Does Not Do
Jev does not explain its answers, and for Plumb that is fine: by design it does not write text. Protection against error is built differently: the confidence threshold, the fallback to the built-in model, Intent's check of the result and Core's verdict. Plumb's agreement does not replace acceptance.
The model is new, so haiku stays the default in the protocol, and jev is switched on by a person's decision after measurement. We will publish accuracy figures when we have them, and until then we do not claim any.
How to Try It
- Update the Forma plugin to the latest version.
- Put
OPENROUTER_API_KEYinto.env. - Tell the agent "connect Jev": it will switch Plumb's executor.
- Set a call limit per cycle and run a measurement on closed cards: prepare the batch, run it with the built-in executor, count the matches.
- Set thresholds for Jev only after the measurement.
Details are in the schema reference, in the Plumb section. Jev's documentation is on the TypeSafe site and on OpenRouter.
Comments